A new methods paper from the GLUCOTYPES team has been published in JACS Au. Led by Adam Urminsky and Juan C. Rojas Echeverri., with Lenka Hernychova and PI Noortje de Haan (Leiden University Medical Center), the study addresses a fundamental quality challenge in glycoproteomics: how reliable are the results produced by automated data analysis tools?
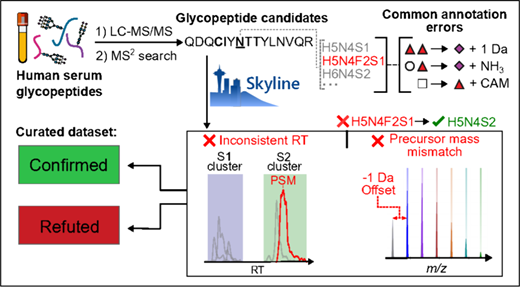
Working with over 3,000 glycopeptide assignments from human serum samples, the team found that more than 56% could not be confirmed upon manual validation — a striking finding that underscores the need for rigorous data curation in the field. In response, they developed and share a step-by-step post-search validation workflow using Skyline software, designed to systematically identify and correct common misassignments in N-glycoproteomics data.
The workflow was developed as part of the data analysis pipeline built within GLUCOTYPES, and the curated dataset is openly available as a resource for future method development, benchmarking, and machine learning efforts.
“In this work we have summarised the data analysis workflow that we have been developing through the GLUCOTYPES project. I would have loved having access to such a guideline when I started in this field!” — Juan C. Rojas E.
Reference: Adam P. Urminsky, Juan C. Rojas E., Lenka Hernychova, Noortje de Haan; Post-Search Validation and Curation of Site-Resolved N-Glycoproteomics Data. JACS Au 2026; https://doi.org/10.1021/jacsau.6c00875